
Codex “stream disconnected before completion”: 4 Variants, 5 Fixes (Tested on 0.167.0)
Codex "stream disconnected before completion" only means the stream ended before response.completed. The tail of the message tells you which of four variants you have. We reproduced two of them, plus the WebSocket fallback, on Codex CLI 0.167.0 with a local mock server, and checked the rest against the official config reference and GitHub issues.
 bufferAbout the author8 min read
“Stream disconnected before completion” in Codex means one thing: the answer was still streaming and the connection ended before Codex got the closing event, response.completed. The tail of the message tells you which of four different situations you’re in: stream closed before response.completed, idle timeout waiting for SSE, websocket closed by server, or Transport error. We reproduced the first two, and the WebSocket fallback, on Codex CLI 0.167.0 against a local mock Responses server. The rest comes from the official config reference and GitHub issues, and each item below says which is which. Here is how to read the message, and what to do for each variant.
What the message means
Codex sends a request to the model service, which streams the answer back piece by piece over SSE or a WebSocket and finishes with a response.completed event. If the stream ends before that event, Codex prints stream disconnected before completion and reconnects on its own. In the terminal you’ll see Reconnecting... 1/5. The retry budget is stream_max_retries in the official configuration reference, with a default of 5.
So Reconnecting... 2/5 is not yet a reason to change settings. A network blip or a connection cut on the server side usually clears on the next attempt. Only a failure after 5/5 needs investigating.
Match the tail of the message
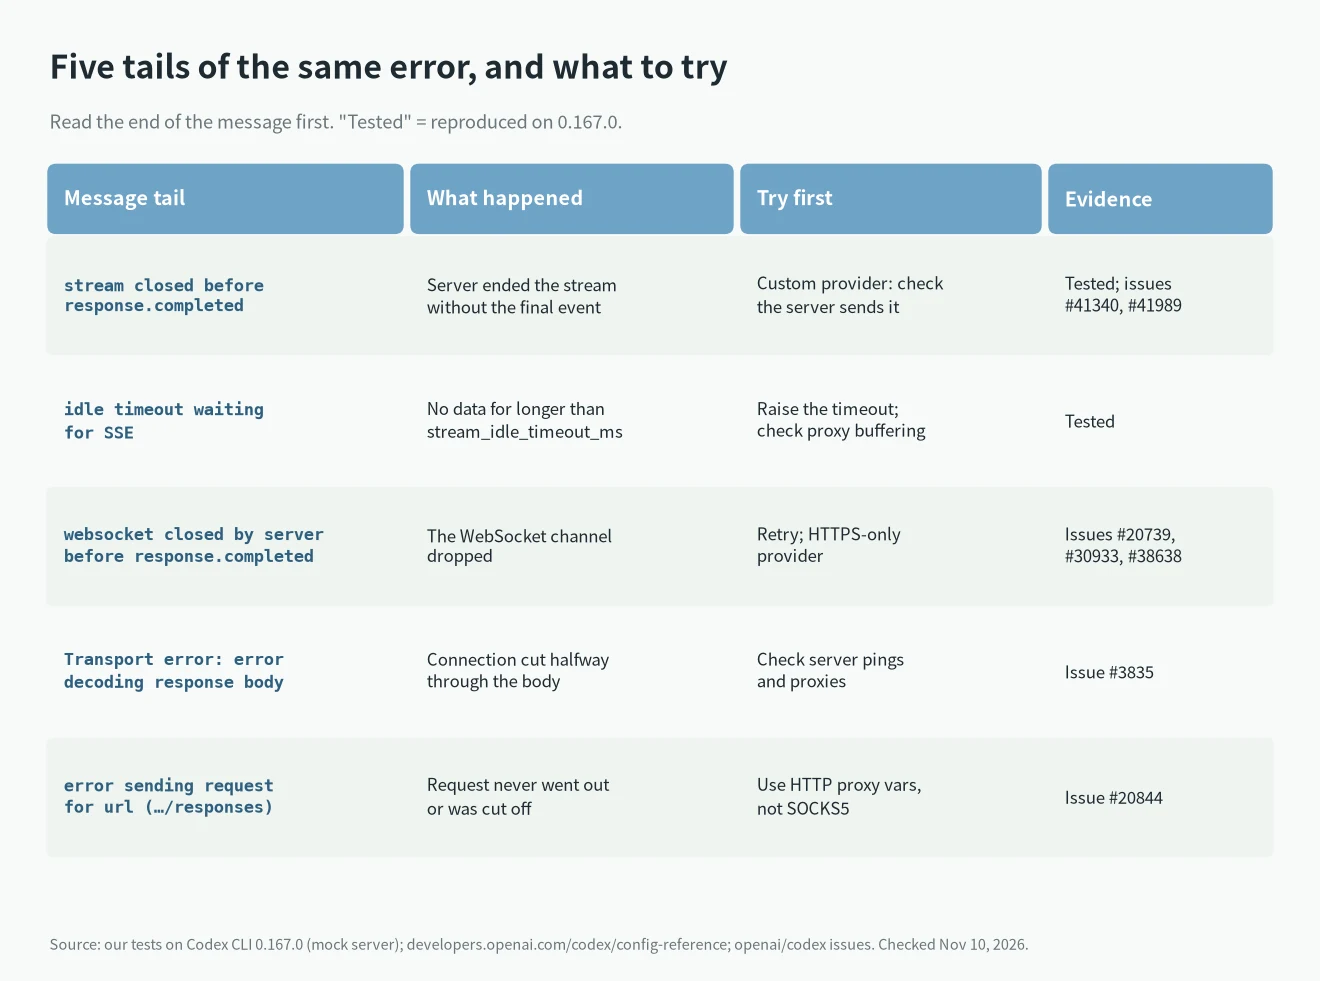
Some detail on each:
stream closed before response.completed: the server closed the connection cleanly but never sent the final event. It’s rare with the official OpenAI login and most common with third-party relays or self-hosted gateways (custom providers). GitHub issues #41340 and #41989 are this case. In #41340 the reporter streamed from the relay with curl and got a complete response ending inresponse.completed, so the gateway isn’t necessarily at fault. Both issues were still open when we looked.idle timeout waiting for SSE: the server sent nothing for longer thanstream_idle_timeout_ms(default 300000 ms, i.e. 5 minutes, per the docs).websocket closed by server before response.completedandidle timeout waiting for websocket: the WebSocket channel dropped. See #20739, #30933 and #38638.Transport error: error decoding response body: the connection was cut halfway through the body. Someone in #3835 traced it to their own server that forwarded the LLM request: its SSE stream paused for about 10 seconds without a ping, and the server sent a FIN to Codex’s HTTP client.error sending request for url (…/responses): the request never went out or was cut off. In #20844, Codex was unstable behind a SOCKS5 proxy (ALL_PROXYand similar) and recovered after switching to an HTTP proxy (HTTP_PROXY/HTTPS_PROXY). That’s from the issue; we didn’t re-test it.
5 things to try
1. Let it retry, then resend
The first few reconnects only tell you the connection dropped once. If it still fails after 5/5, resend your last prompt, or run codex resume to pick up the previous session. One caution: reconnects happen inside the same turn, so after you interrupt with esc the state of that turn may be unclear. The reporter of #30933 raised exactly that.
2. Run codex doctor to check the provider URL
Version 0.167.0 ships codex doctor. We pointed a provider’s base_url at a port nobody was listening on, and its reachability line showed ✗ “one or more required provider endpoints are unreachable over HTTP”, suggested checking proxy, VPN, firewall, DNS and custom CA settings, and printed connect failed on the provider’s line. With a server listening, it showed reachable. Rule this layer out first.
3. Third-party provider: confirm the server sends response.completed
A custom provider has to speak the Responses protocol (wire_api = "responses", which the docs list as the only supported value). Call the relay’s /responses endpoint with curl and streaming enabled, and check that response.completed arrives at the end. If it doesn’t, the relay needs fixing. If it does and Codex still fails, as in #41340, try another Codex version and add your version and provider to the issue. A gateway that buffers the stream or cuts idle connections can also produce idle timeout or Transport error, which is what happened in #3835.
4. Raise the idle timeout and retry count (custom providers only)
[model_providers.my-gateway]
name = "my-gateway"
base_url = "https://example.com/v1"
env_key = "MY_GATEWAY_KEY"
wire_api = "responses"
stream_idle_timeout_ms = 600000
stream_max_retries = 8
The reference gives defaults of 300000 and 5 for these two keys. In our test, setting the timeout to 3000 made Codex report idle timeout waiting for SSE after about 3 seconds, and setting retries to 2 showed only 1/2 and 2/2, so both keys take effect. They apply to custom providers only: the built-in openai provider can’t be overridden (the docs list openai, ollama and lmstudio as reserved IDs).
5. Seeing Reconnecting 1/5 to 5/5 before it finally works: turn off WebSocket
The default provider tries WebSocket first. If the connection fails or a proxy blocks it, each failure counts as a reconnect, and Codex only falls back to HTTPS after the retries run out. We tested this against a mock server with no WebSocket support: with supports_websockets = true the terminal printed 2/5 through 5/5, then Falling back from WebSockets to HTTPS transport, and the whole command took about 8 seconds. With false it went straight to HTTPS in about 1.4 seconds. In real setups, the reporter of #22634 measured about 75 extra seconds on Windows, because each WebSocket attempt times out after 15 seconds and there are 5 attempts. #19821 says this is common for people behind proxies.
The workaround in issues #13103 and #22634 is an HTTPS-only custom provider that keeps your ChatGPT login:
model_provider = "openai_http"

[model_providers.openai_http]
name = "OpenAI HTTP only"
wire_api = "responses"
requires_openai_auth = true
supports_websockets = false
base_url = "https://chatgpt.com/backend-api/codex"
Caveats: this is a community workaround from issue comments, not a recommendation in the official docs. Someone in #13103 warns that this provider may not inherit every feature of the official one. The responses_websockets feature flag is listed as removed in 0.167.0 (we saw that in codex features list), so you can’t switch it off through features anymore. We confirmed 0.167.0 reads this config and sends the request to that HTTPS URL (it returned 401 because we weren’t logged in). We did not run a full turn with a real ChatGPT account.
What we tested and what is from the docs
We installed Codex CLI 0.167.0 on Linux, wrote a small Python mock of a Responses server, pointed codex exec at it through a custom provider, and made the server finish normally, close the connection after the first piece of text, or go silent after the first piece of text.
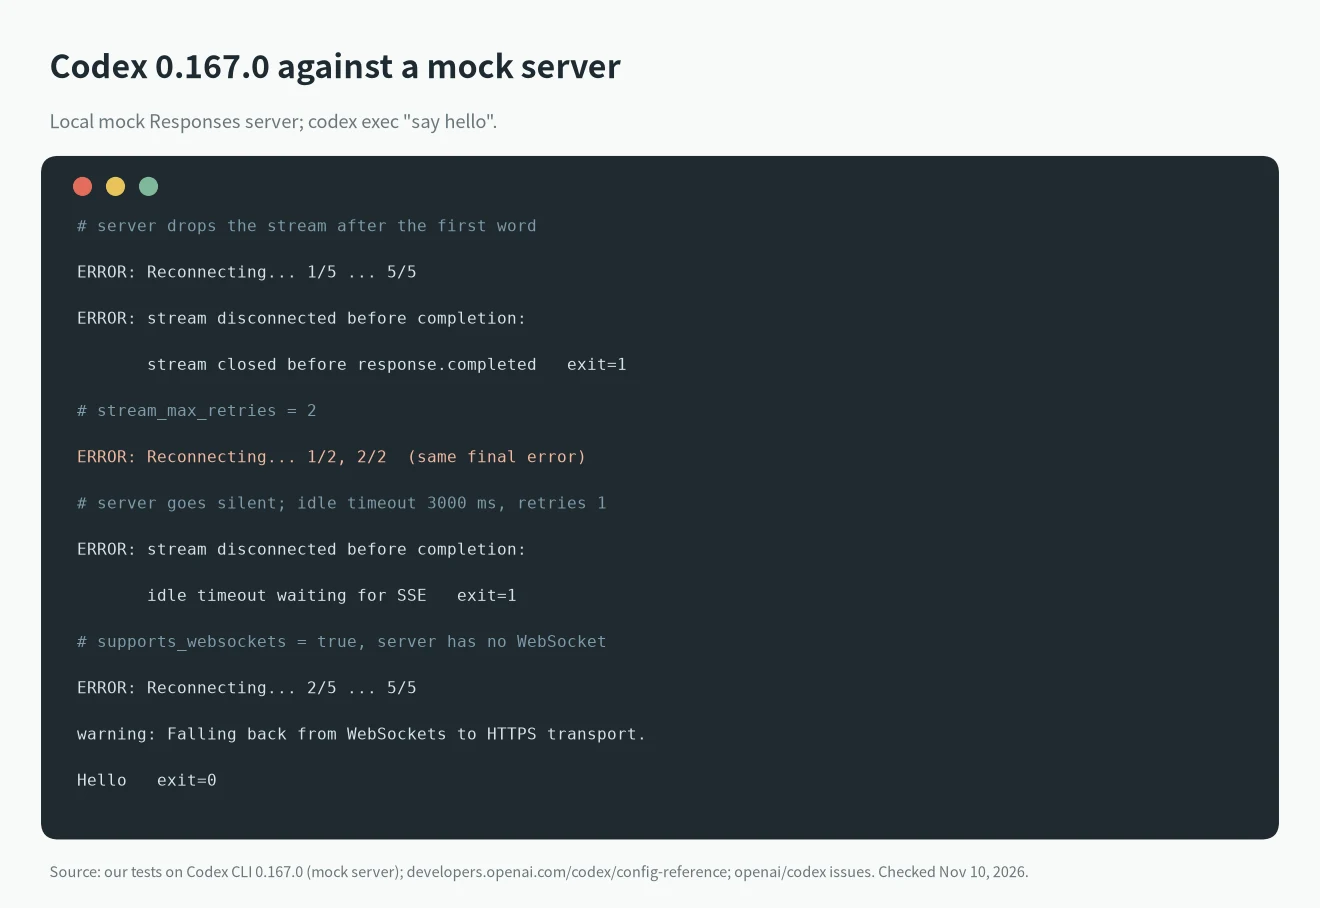
This shows when the message appears and whether the retry and timeout settings work. It can’t tell you why a real service (OpenAI or a relay) drops a stream, and it doesn’t cover Windows, macOS, proxies or a real WebSocket drop.
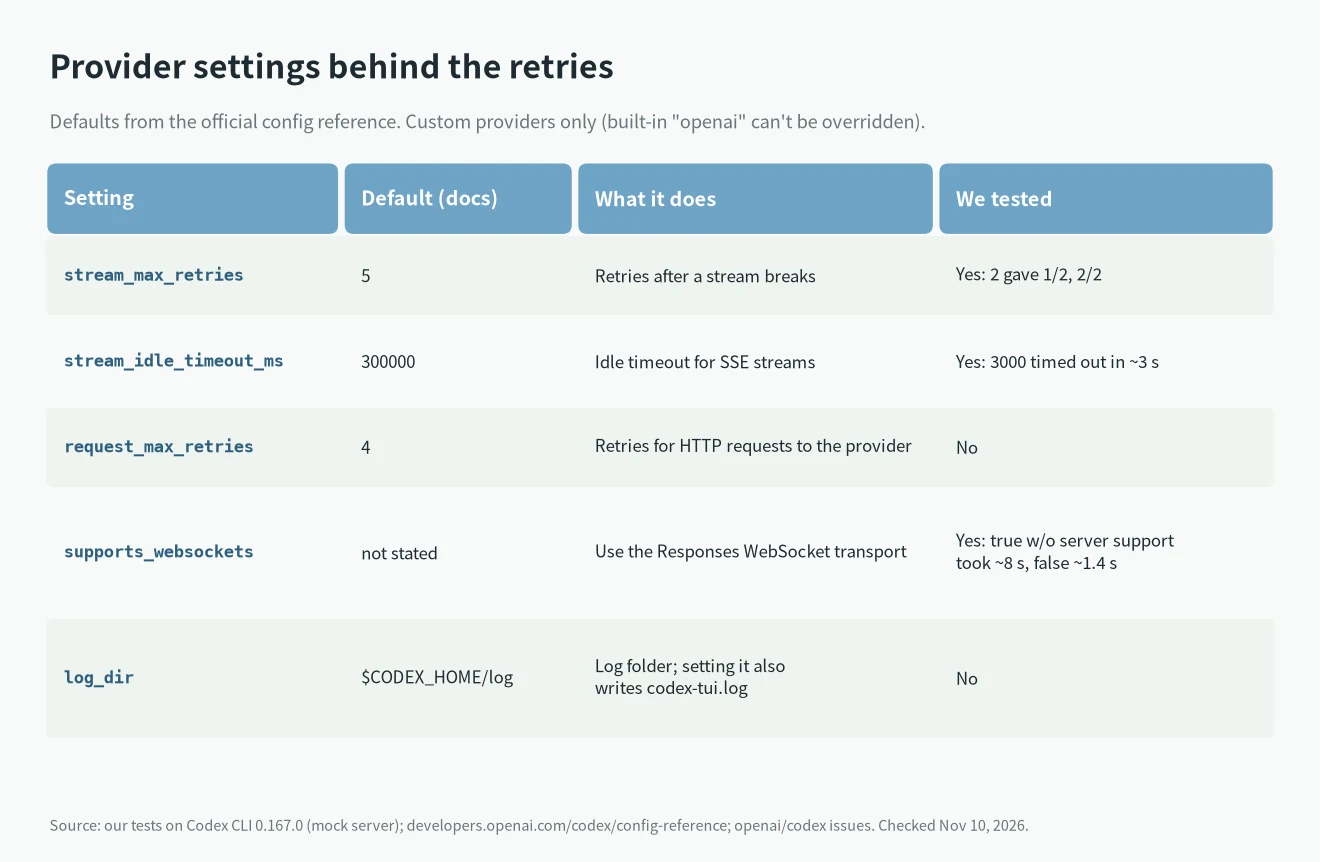
- Tested:
stream closed before response.completed,idle timeout waiting for SSE, theReconnecting n/Ncounts, the WebSocket fallback, thecodex doctorreachability hint, andremovedinfeatures list. - From the docs or issues, not re-tested: defaults of each setting, real WebSocket drops, the SOCKS5 proxy problem, how specific relays behave.
- Sources: Codex Configuration Reference, plus openai/codex issues #3835, #13103, #19821, #20739, #20844, #22634, #30933, #38638, #41340 and #41989. Looked up November 10, 2026.
For other Codex messages, see OpenAI Codex error codes. For login problems, see Codex token exchange failed (403) and localhost refused to connect. The other overload message is covered in Selected model is at capacity. For limits, see the Claude and Codex usage limit tracker.
FAQ
Does “stream disconnected before completion” mean my account is restricted?
No. Quota and rate limits normally come with an explicit message. This one only says the stream ended early and doesn’t mention your account.
Why does it keep showing Reconnecting 1/5 to 5/5?
5 is the default stream_max_retries. Codex reconnects after each drop and only reports the final error when the budget is used up. On the WebSocket path, each failed attempt also counts, and the HTTPS fallback comes last.
Is it a Codex bug or my network?
Read the tail. connect failed, a SOCKS5 proxy or a blocked WebSocket usually point to the network. If curl works against your custom provider but Codex fails, it looks more like a client or version issue, as in #41340 and #41989, which were both still open when we checked.
Can it happen with the official OpenAI login?
Yes. The reporters of #20739 and #30933 used the official provider over WebSocket and saw websocket closed by server before response.completed.
How do I get more detailed logs?
Per the reference, log_dir defaults to $CODEX_HOME/log, and setting it explicitly also writes a plaintext TUI log, codex-tui.log. Remove tokens and paths before pasting logs into an issue.