

Muse Ember Price Math: Same List Price as Haiku 5.5, About One-Third AA Cost per Task (Still Behind on FrontierCode)
Muse Ember matches Claude Haiku 5.5 list prices, but AA Intelligence Index cost per task is about one third; it still trails on FrontierCode 2.0. Figures from Meta, Artificial Analysis, and Anthropic.
 bufferAbout the author4 min read
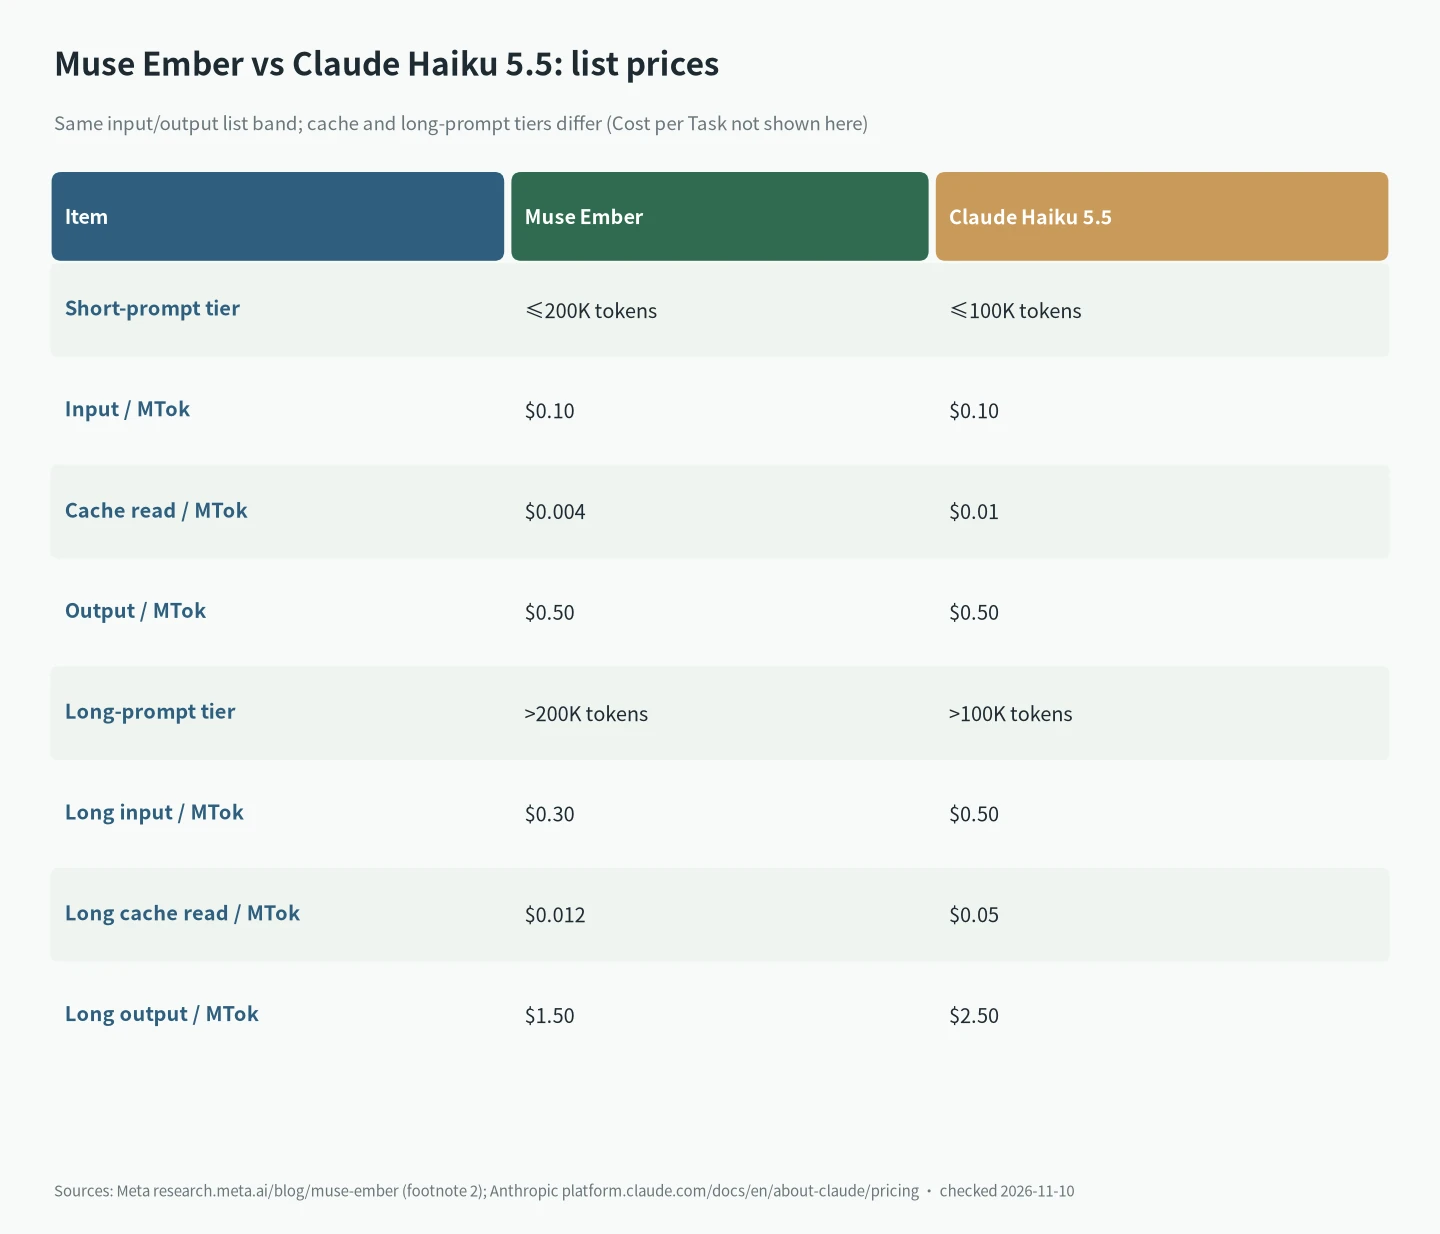
Checked 10 Nov 2026 (Beijing). Meta’s smallest efficient model, Muse Ember, launched in the early hours of 10 Nov 2026 Beijing time. Its input/output list prices match Claude Haiku 5.5 and GPT-6 Luna ($0.10 / $0.50 per MTok), but on the Artificial Analysis Intelligence Index, Ember (max) costs about $0.14 per task versus about $0.41 for Haiku 5.5 (max)—roughly one third. Hard boundary first: on FrontierCode 2.0-AA, Ember scores 27.2% and Haiku 34.9%, so it still trails on mergeability-graded engineering work. Figures below come only from the Meta blog, Artificial Analysis, and Anthropic pricing.
What it is and who it is for
Per the Meta research blog, Muse Ember targets the work agents repeat all day: tool calls, coding subtasks, routing, extraction, and long-document parsing. The API id is muse-ember-1.0, available on Muse Code and the Meta Model API, with a 1M-token context and up to about 512K output tokens. Meta’s own framing: Muse Wonder plans the hard parts; Ember handles volume.
List prices: what “same price” means
In the short-prompt tier, Ember (≤200K) and Haiku 5.5 (≤100K) share the same input and output list prices: $0.10 / $0.50 per MTok. Cache reads differ—Ember $0.004 vs Haiku $0.01 (Meta blog, Anthropic pricing). Long-prompt markups start at different thresholds: Ember above 200K at $0.30 / $0.012 / $1.50; Haiku above 100K at $0.50 / $0.05 / $2.50.
The math: why ~one third per task
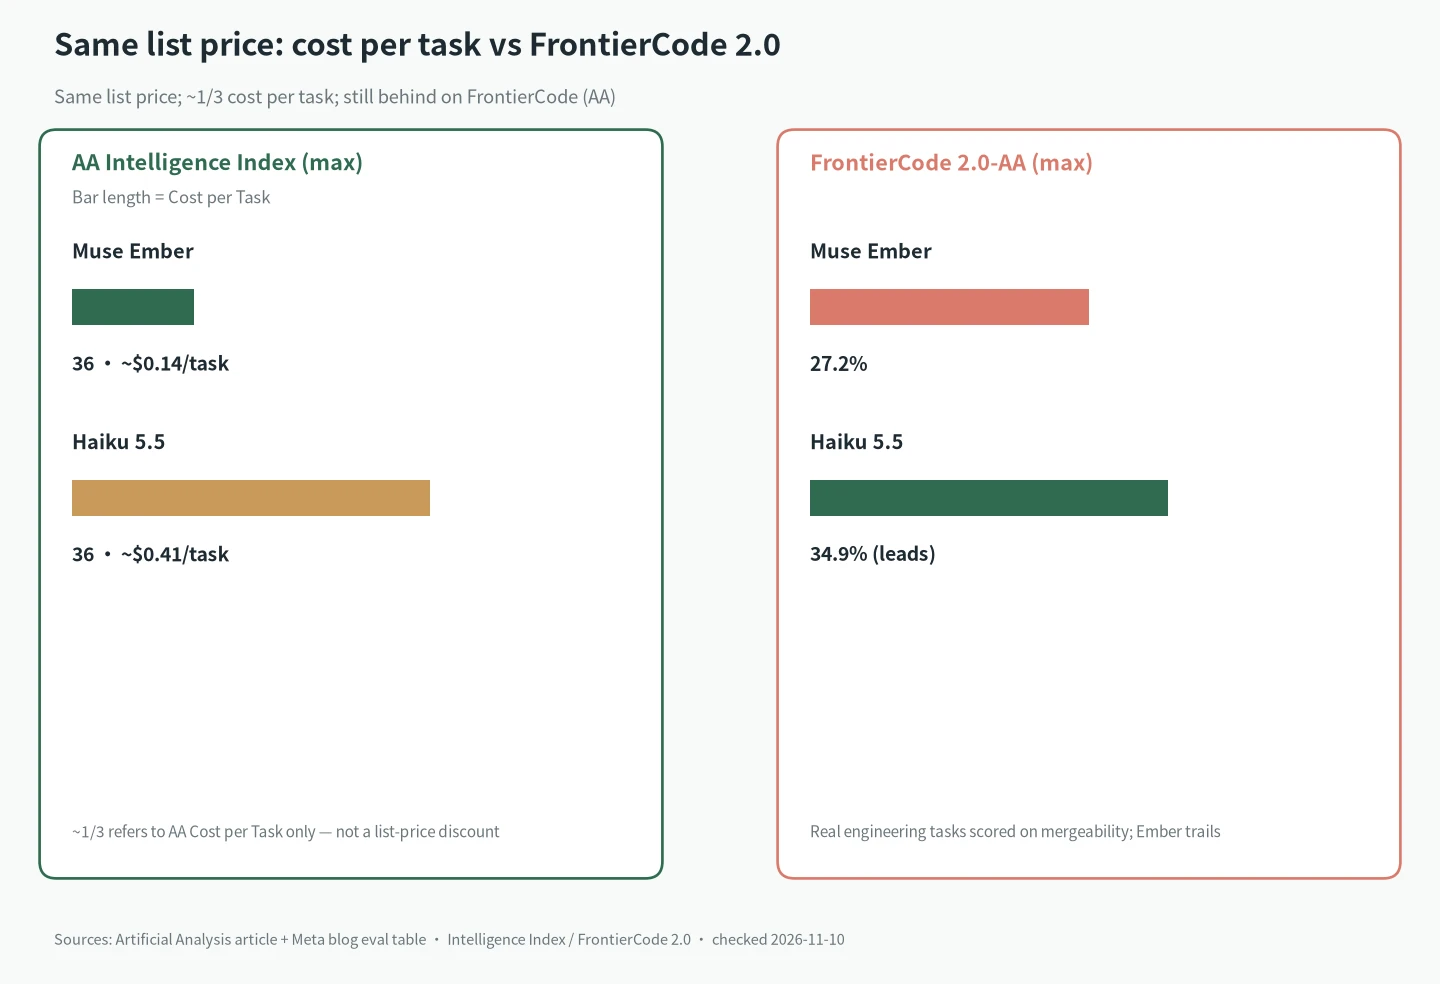
“About one third” refers only to Cost per Task on the Artificial Analysis Intelligence Index, not a list-price discount. Per the AA article and model release page, Ember (max) scores 36 at about $0.14 per task; Haiku 5.5 (max) also scores 36 at about $0.41 (about 2.9×). AA attributes the gap to roughly 60% cheaper cached input and about one third as many output tokens as Haiku (max). At xhigh, Ember is 34 for about $0.12 per task.
Where it loses: FrontierCode 2.0
On FrontierCode 2.0-AA (real engineering tasks scored on mergeability), the Meta blog and AA article agree: Ember (max) 27.2%, Haiku 5.5 (max) 34.9%, GPT-6 Luna (max) 25.2%. That is not a full Haiku substitute, and it is not an overall win. Ember is competitive for high-volume subtasks when Index cost per task matters; merge-hard engineering work may still favor Haiku.
Other AA results: mixed
Coding Agent Index-AA (each model in its own agent—not bare-model scores): Ember (max) in Muse Code scores 46, Haiku 5.5 (max) in Claude Code 37, Luna (max) in Codex 31 (Meta blog and AA article).
GDP.pdf-AA: Ember and Luna both 22.8%, Haiku 20.8%. On Terminal-Bench 4.0, Ember (max) is 40.9% in both Meta and AA; Haiku’s side is 39.2% in Meta’s “best published harness” table and 32.8% in the AA Index article, so this article does not treat Haiku’s Terminal-Bench figure as a single settled number. AA calls AutomationBench-AA a highlight for Ember, but Meta’s table and AA’s article disagree on the percentage, so no AutomationBench percentage appears here.
Knowledge shortcoming: AA-Omniscience
Per the AA article, Ember’s AA-Omniscience v1.1 accuracy is about 21.1%, below Haiku 5.5 (max) at 34.7% among the similarly intelligent models AA compared. That is mostly because it declines about 64% of questions, which keeps its hallucination rate around 17.4%—about half of Haiku (max). Treat this as a knowledge gap, not evidence of an overall win; fact-seeking workloads should account for it.
Where it sits vs Spark and Wonder
Meta’s table: Ember (max) Index 36 at about $0.14 per task; Muse Spark 1.3 (max) Index 37 at about $2.39. AA: Muse Wonder (max) Index 44 at about $6.95 per task—Ember is about 8 points lower at roughly 1/50th the task cost. Role split stays: Wonder for hard problems, Spark for coding/agent workflows, Ember for repeatable execution.
How to access it (public channels)
Official paths: Muse Code and the Meta Model API (muse-ember-1.0). It is also listed on Google Cloud Partner Models; the Meta blog also mentions Oracle Cloud. OpenRouter lists meta/muse-ember at the same $0.10 / $0.50. Whether mainland China networks can reach Meta, Google Cloud, or OpenRouter Muse endpoints stably is UNVERIFIED against an official regional statement; this article includes no bypass or region-workaround steps.
FAQ
Is the list price cheaper than Haiku? No. Short-tier input/output are both $0.10 / $0.50.
What does “one third” mean? Only Artificial Analysis Intelligence Index Cost per Task (~$0.14 vs ~$0.41), not a list-price cut.
Is it a Haiku substitute? Same Index score, lower task cost; still behind on FrontierCode 2.0—use by scenario, not as a blanket swap.
Open weights? Meta’s launch materials do not provide an open-weight download.
Access from China? Public channels above; mainland reachability is unverified—follow official availability where you run.